If vLLM already solved LLM serving, why did SGLang appear?
Stay ahead of the curve with our blogs, where the latest market intel, product comparison, AI trends, innovations, and breakthroughs come to life. Get a front-row seat to the future of AI, with insights that help you think smarter, move faster, and innovate bolder. Read on to let the ideas spark your next big move.
Back to Blog Home Table of Content India announced a serious bet on AI infrastructure with the IndiaAI Mission, committing over ₹10,000 crore to build a national compute layer – GPUs that Indian startups, researchers, and enterprises could access at subsidized rates rather than paying global market prices in dollars. On paper, the numbers looked […]
Back to Blog Home Table of Content It is quite common to think that Sovereign AI is just about where your data lives. However, true sovereignty is about having control over your digital world, not just a local storage spot. This is significant for leaders to factor as they work with global data rules. Where […]
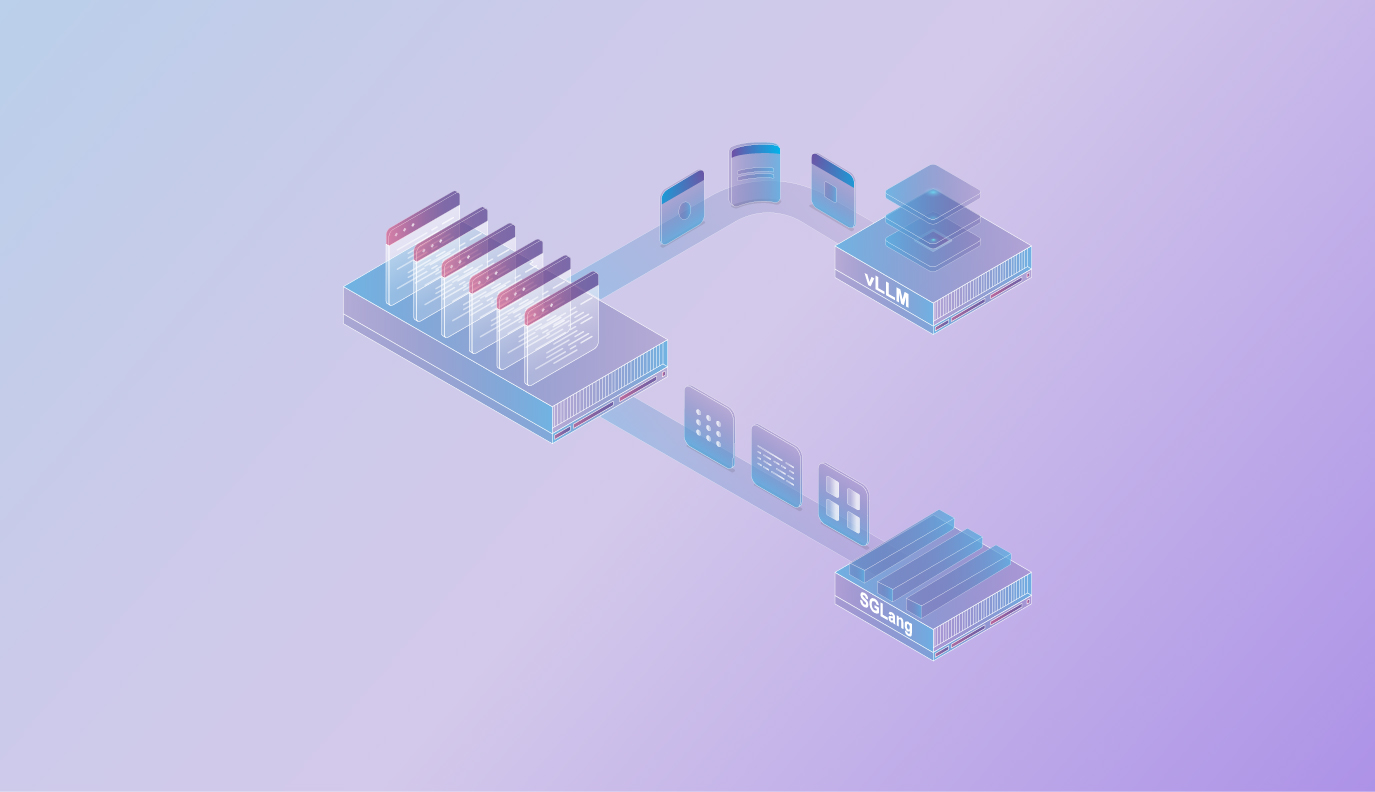
Explore the vLLM vs SGLang benchmarks to understand performance differences in LLMs and framework comparisons.
Continuing the series, this one compares between two inference engines, SGLang and vLLM, and provides guidance on choosing the right one based on project requirements. Use this as guide to drive your decisions.
The emergence of vLLM improved GPU utilization for AI model serving, addressing issues like memory fragmentation. However, as workloads evolved towards complex multi-turn interactions, SGLang was developed to optimize prefix caching, reducing unnecessary computations. This ensures higher efficiency, lower latency, and reliable structured outputs such as JSON, enhancing modern AI applications.

SGLang and vLLM are two tools developed to enhance the efficiency of using open-source AI models. While vLLM addresses resource wastage in AI model hosting, SGLang improves response times by minimizing repetition in processing requests. Here’s a read to help you decide which one is better.
Most AI teams track model accuracy, inference cost, and latency. Almost none track how long it took to get the first version live, which is often the number that decides whether the project survives at all.