B300 in Production: What 18 Benchmark Runs Actually Showed
Full-stack AI acceleration cloud
Enforce security policy on all LLM endpoints
Platform Architecture & Design
Inside the Velocis architecture
EXPLORE THE PLATFORM
Unified Monitoring & Management
Live telemetry across GPU clusters
End-to-end MLOps, automated
AI Platform-as-a-Service (AI PaaS)
Train and scale AI on managed infra
AI-native apps and agents, ready to deploy
Deploy open-source LLMs managed endpoints
Centralized control over your entire AI stack
NVIDIA & AMD GPUs on bare metal, VM, or K8
Protect AI environments and models

Tour the
SOLUTIONS BY INDUSTRY
Fraud, risk, and document AI for BFSI
Rethink underwriting and claims with AI
AI for recommendations, pricing, and demand
AI for design, simulation, and smart factories
Technical Education & Research
AI Cloud for research labs and learning
Scalable AI Cloud for AI-native teams
Have a use case in mind?

Community
Find your fellow builders’ tribe
Watch
READ
Perspectives on AI, infra, and the market
Deep research and technical perspectives
How customers build AI with Neysa
JOIN
Join Neysa events and webinars
FEATURED
Full-stack AI acceleration cloud
Enforce security policy on all LLM endpoints
Platform Architecture & Design
Inside the Velocis architecture
EXPLORE THE PLATFORM
Unified Monitoring & Management
Live telemetry across GPU clusters
End-to-end MLOps, automated
AI Platform-as-a-Service (AI PaaS)
Train and scale AI on managed infra
AI-native apps and agents, ready to deploy
Deploy open-source LLMs managed endpoints
Centralized control over your entire AI stack
NVIDIA & AMD GPUs on bare metal, VM, or K8
Protect AI environments and models
Tour the
SOLUTIONS BY INDUSTRY
Fraud, risk, and document AI for BFSI
Rethink underwriting and claims with AI
AI for recommendations, pricing, and demand
AI for design, simulation, and smart factories
Technical Education & Research
AI Cloud for research labs and learning
Scalable AI Cloud for AI-native teams
Have a use case in mind?
Community
Find your fellow builders’ tribe
Watch
READ
Perspectives on AI, infra, and the market
Deep research and technical perspectives
How customers build AI with Neysa
JOIN
Join Neysa events and webinars
FEATURED
Full-stack AI acceleration cloud
Enforce security policy on all LLM endpoints
Platform Architecture & Design
Inside the Velocis architecture
EXPLORE THE PLATFORM
Unified Monitoring & Management
Live telemetry across GPU clusters
End-to-end MLOps, automated
AI Platform-as-a-Service (AI PaaS)
Train and scale AI on managed infra
AI-native apps and agents, ready to deploy
Deploy open-source LLMs managed endpoints
Centralized control over your entire AI stack
NVIDIA & AMD GPUs on bare metal, VM, or K8
Protect AI environments and models
Tour the
SOLUTIONS BY INDUSTRY
Fraud, risk, and document AI for BFSI
Rethink underwriting and claims with AI
AI for recommendations, pricing, and demand
AI for design, simulation, and smart factories
Technical Education & Research
AI Cloud for research labs and learning
Scalable AI Cloud for AI-native teams
Have a use case in mind?
Community
Find your fellow builders’ tribe
Watch
READ
Perspectives on AI, infra, and the market
Deep research and technical perspectives
How customers build AI with Neysa
JOIN
Join Neysa events and webinars
FEATURED
Modular, cloud-agnostic, and microservices-first — Neysa Velocis gives your teams speed, control, and freedom to innovate without infrastructure drag.

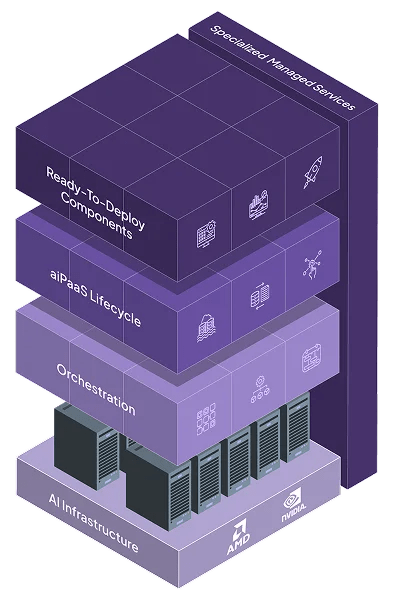
At the heart of Neysa Velocis is a flexible, distributed architecture built to abstract away infrastructure complexity — while providing complete control, visibility, and extensibility for technical users.
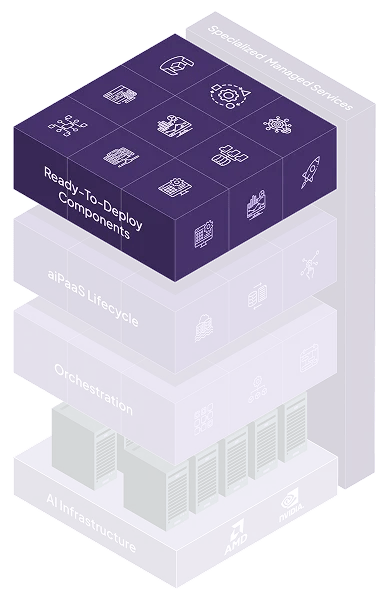
 Full-service AI infrastructure and resource management
 Continuous performance monitoring and optimization
 Dedicated MLOps support and collaborative solution building
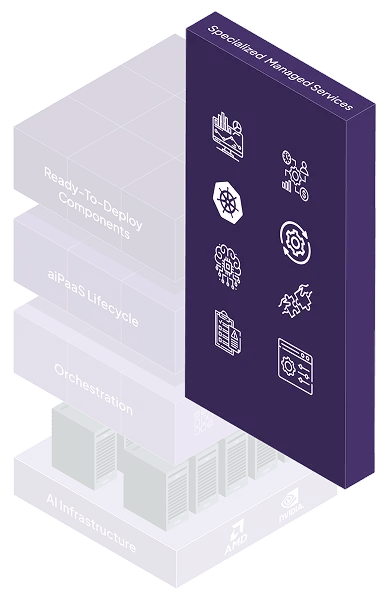
 Pre-built APIs for OCR, NLP, and Computer Vision
 Instantly deploy and scale your custom LLMs
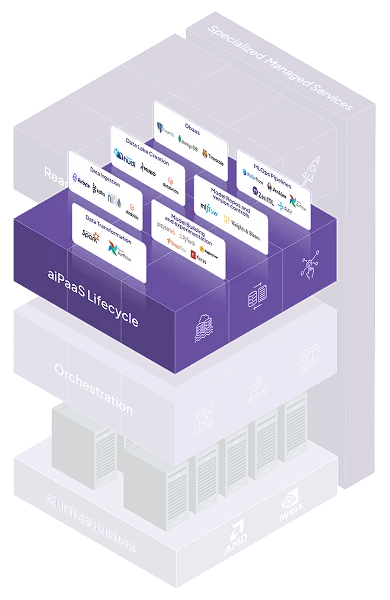
 An end-to-end, framework-agnostic platform for the entire ML lifecycle from data ingestion to inference
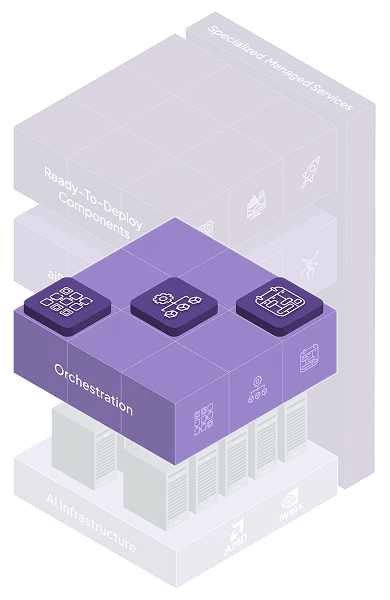
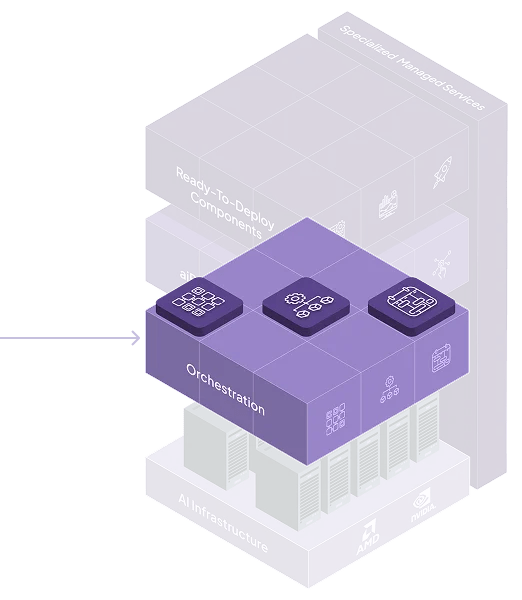
 AI Cluster Management
 AI Scheduler
 Resource Manager
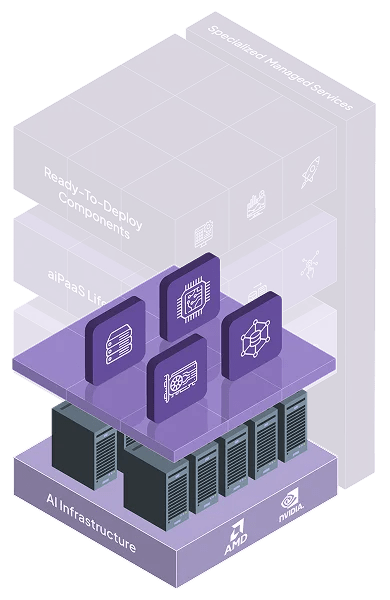
 GPUs: Bare Metals | Virtual Machines | Containers
 CPUs
 Storage: Object | Block | NFS
 Networks
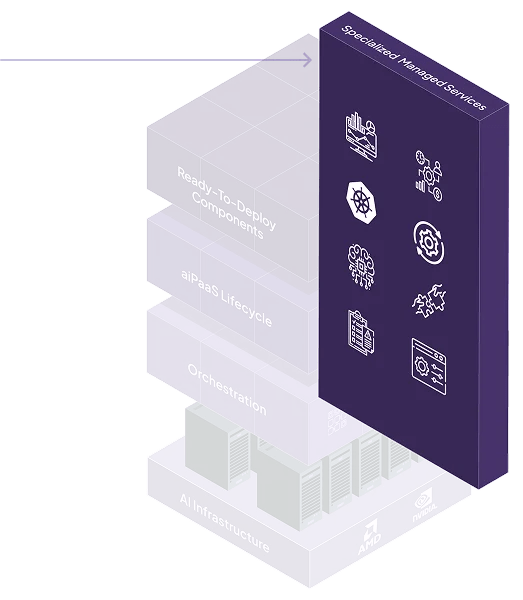
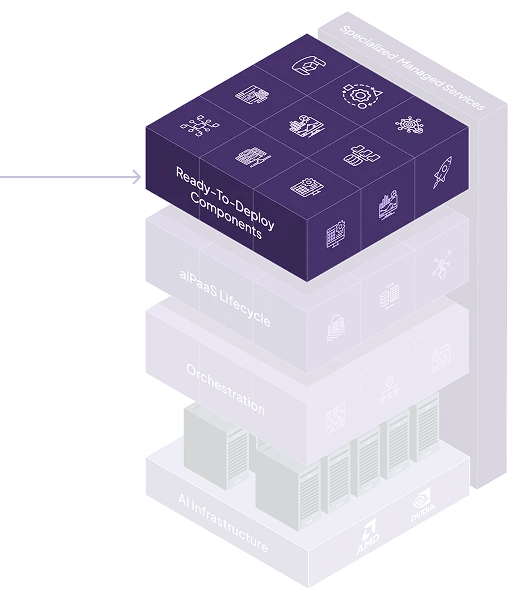
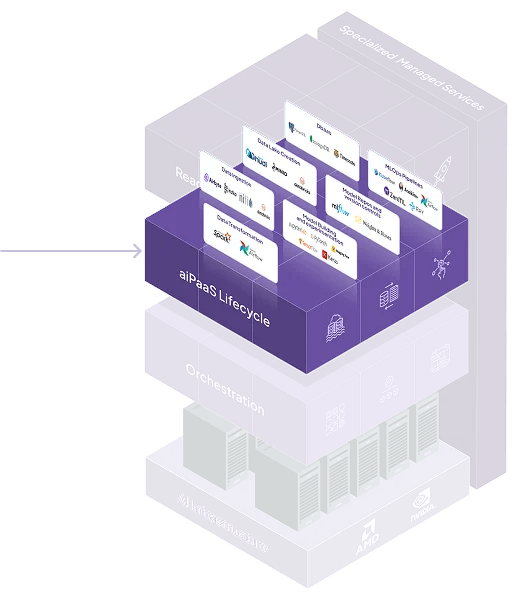
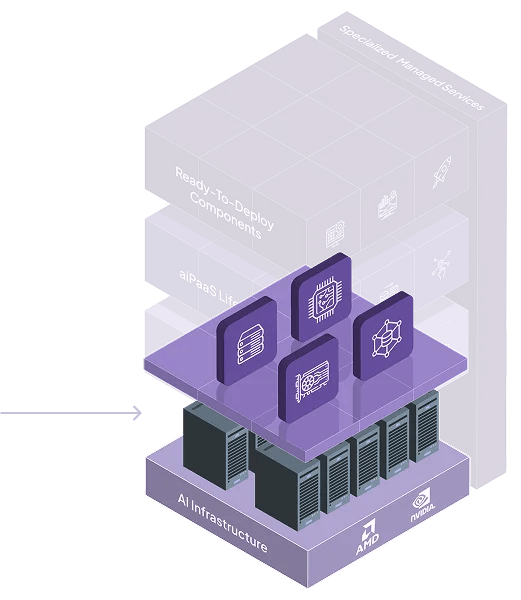

Full-service AI infrastructure and resource management
Continuous performance monitoring and optimization
Dedicated MLOps support and collaborative solution building
Pre-built APIs for OCR, NLP, and Computer Vision
Instantly deploy and scale your custom LLMs
An end-to-end, framework-agnostic platform for the entire ML lifecycle from data ingestion to inference
AI Cluster Management
AI Scheduler
Resource Manager
GPUs: Bare Metals | Virtual Machines | Containers
CPUs
Storage: Object | Block | NFS
Networks
Every layer of Neysa Velocis is modular, API-driven, and secure by design — giving developers the flexibility to move fast and stay in control.

Every core function is exposed via secure APIs. Integrate Velocis with your CI/CD pipelines, monitoring stacks, IDEs, and existing ML workflows.

Every component enforces zero-trust principles, role-based access, and encrypted communication — governed by our zero trust security framework.

Pick what you need — GPUaaS, PaaS, Inference — without being forced into a monolithic stack. Each layer is independently consumable but deeply interoperable.

Each function-provisioning, training, inference, logging-runs as a scalable, independently deployable service, enabling horizontal scaling and fault isolation.

Deploy on Neysa Velocis’s public AI cloud, in your private cluster, or in a hybrid mode — with consistent experience and orchestration across environments.
Every core function is exposed via secure APIs. Integrate Velocis with your CI/CD pipelines, monitoring stacks, IDEs, and existing ML workflows.
Every component enforces zero-trust principles, role-based access, and encrypted communication — governed by our zero trust security framework.
Pick what you need — GPUaaS, PaaS, Inference — without being forced into a monolithic stack. Each layer is independently consumable but deeply interoperable.
Each function-provisioning, training, inference, logging-runs as a scalable, independently deployable service, enabling horizontal scaling and fault isolation.
Deploy on Neysa Velocis’s public AI cloud, in your private cluster, or in a hybrid mode — with consistent experience and orchestration across environments.
Neysa Velocis delivers real-world architectural advantages — from zero-downtime scaling to plug-and-play inference pipelines.

Scale GPU clusters, training pipelines, or inference endpoints independently — without changing your code or workflows.

Built-in redundancy, load balancing, and observability across all services. No single point of failure.

Pre-integrated orchestration, pipelines, and inference layers reduce time from model prototyping to deployment — dramatically.

Connects easily with enterprise IAM, data lakes, log aggregators, and VPCs. Compatible with industry-standard tools and frameworks (e.g., Git, Docker, MLflow, Kubeflow, Airflow).

Designed to evolve — support for new GPU SKUs, model formats, and AI paradigms (like agents, fine-tuning, vector DBs) is built into the product roadmap.
Scale GPU clusters, training pipelines, or inference endpoints independently — without changing your code or workflows.
Built-in redundancy, load balancing, and observability across all services. No single point of failure.
Pre-integrated orchestration, pipelines, and inference layers reduce time from model prototyping to deployment — dramatically.
Connects easily with enterprise IAM, data lakes, log aggregators, and VPCs. Compatible with industry-standard tools and frameworks (e.g., Git, Docker, MLflow, Kubeflow, Airflow).
Designed to evolve — support for new GPU SKUs, model formats, and AI paradigms (like agents, fine-tuning, vector DBs) is built into the product roadmap.
Whether it’s Git, MLflow, or your IAM system — Velocis plugs in fast, plays well across clouds, and brings your workflows up to speed.
SSO, SAML, LDAP, RBAC
S3, Azure Blob, HDFS, NFS, Weka
GitHub/GitLab, MLflow, Docker, Kubeflow
SIEM tools, policy enforcement engines
Public/Private cloud, hybrid deployments, VPC support
Speak with a solution architect, explore the API docs, or test-drive the platform with your own workloads.
We use cookies on neysa.ai to deliver a reliable and personalised experience. Some cookies are essential for the site to function; others help us understand how visitors use our platform. You can manage your preferences at any time. For full details, see our Privacy Policy.
Your Privacy